|
UNIT-2 |
||||||||||||||||||||||||
|
TOPIC: Syntax Analysis & Syntax
Directed Translation |
||||||||||||||||||||||||
|
UNIT-2/Lecture-01 |
||||||||||||||||||||||||
|
CFG: Context-Free Grammars: [RGPV, Dec 2013] A GFG is consisting of 4-tuple G = (V, T, P, S)
where 1. V is the (finite) set
of variables (or non-terminals). Each variable represents a language, i.e.,
a set of strings. 2. T is a finite set of
terminals, i.e., the symbols that form the strings of the language
being defined. (T is disjoint from V) 3. P is a set of
production rules that represent the recursive definition of the language. 4. S ε V is the start symbol that
represents the language being defined. Each production rule consists of: 1. A
variable that is being (partially) defined by the production. This variable
is often called the head of the production. 2. The
production symbol → 3. A
string of zero or more terminals and variables. Example of CFG: Given a grammar G = ({S},
{a, b}, P, S). The set of productions P is S
→aSb S
→SS S→ ε This grammar generates strings
such as abab, aaabbb, and aababb. If we assume that a
is left parenthesis ‘(’ and b is right parenthesis ‘)’, then L(G)
is the language of all strings of properly nested parentheses. DERIVATION TREES:
A ‘derivation tree’ is an
ordered tree which the the nodes are labeled with the left sides of
productions and in which the children of a node represent its corresponding
right sides. Definition of a Derivation Tree Let G = (V, T,
S, P) be a CFG. An ordered tree is a derivation tree for G iff
it has the following properties: (i) The root of the
derivation tree is S. (ii) Each and every leaf
in the tree has a label from T U{ λ} (iii) Each and every
interior vertex (a vertex which is no a leaf) has a label from V. (iv) If a vertex has label
AεV, and its children are
labeled (from left to right) a1 , a2 , KK an, then P must
contain a production of the form A→ a1, a2…………
an (v) A leaf labeled l has
no siblings, that is, a vertex with a child labeled l can have no other
children. Sentential Form: For a given CFG with productions S →aA,
A→ aB, B→ bB, B→ a.
The derivation tree is as shown below. The
resultant of the derivation tree is the word w = aaba. This is
said to be in “Sentential Form”. Left Most Derivation Right Most Derivation: Consider
the grammar G with production 1.
S→aSS 2. S→b For the String w = aababbb,
We have: The
sequence followed is “left-most derivation”, following “1121222”, giving, “aababbb”. The sequence
1211222 represents a “Right Most Derivation”, giving, “aababbb”. Example:
A grammar G which is
context-free has the productions Obtain the derivation tree. Reference:
{Compilers: Principles, Techniques and Tools. Page No: 165-170}
|
||||||||||||||||||||||||
|
Unit-02/Lecture-02 |
||||||||||||||||||||||||
|
Ambiguity in Grammar: [RGPV, June 2009, Dec
2005] The grammar given by Generates strings having an
equal number of a’s and b’s. The string “abab” can be
generated from this grammar in two distinct ways, as shown in the following derivation
trees: Similarly, “abab” has
two distinct leftmost derivations: Also, “abab” has two
distinct rightmost derivations: Each of the above derivation trees can be turned into a unique rightmost
derivation, or into a unique leftmost derivation. Each leftmost or rightmost
derivation can be turned into a unique derivation tree. These representations
are largely interchangeable. Ambiguous Grammars and
Ambiguous Languages: Since derivation trees,
leftmost derivations, and rightmost derivations are equivalent rotations, the
following definitions are equivalent: Definition: Let G = (N, T, P, S) be a CFG. A string w ε L(G) is said to be
“ambiguously derivable “if there are two or more different derivation trees
for that string in G. Definition: A CFG given by G = (N,
T, P, S) is said to be “ambiguous” if
there exists at least one string in L(G) which is ambiguously
derivable. Otherwise it is unambiguous. Ambiguity is a property of a
grammar, and it is usually, but not always possible to find an equivalent
unambiguous grammar. An “inherently ambiguous language” is a language for
which no unambiguous grammar exists Example: Show that the grammar S → SbS, S → a is ambiguous. Solution: In order to show that G is
ambiguous, we need to find a wεL(G), which is ambiguous. Assume w = abababa. The two
derivation trees for w = abababa is shown below in Fig. (a) and
(b). Therefore, the grammar G is
ambiguous. Syntax analysis: The syntax analysis
phase of a compiler will take a string of tokens produced by the lexer, and
from this construct a syntax tree for the string by finding a derivation of
the string from the start symbol of the grammar. This can be done by guessing
derivations until the right one is found, but random guessing is hardly an
effective method. Even so, some parsing techniques are based on “guessing”
derivations. However, these make sure, by looking at the string, that they
will always guess right. These are called predictive parsing methods. Predictive
parsers always build the syntax tree from the root down to the leaves And are
hence also called (deterministic) top-down parsers. Other parsers go the
other way: They search for parts of the input string that matches right-hand
sides of productions and rewrite these to the left-hand non-terminals, at the
same time building pieces of the syntax tree. The syntax tree is eventually
completed when the string has been rewritten (by inverse derivation) to the
start symbol. Also here, we wish to make sure that we always pick the “right”
rewrites, so we get deterministic parsing. Such methods are called bottom-up
parsing methods. ROLE OF THE PARSER Parser obtains a
string of tokens from the lexical analyzer and verifies that it can be
generated by the language for the source program. The parser should report
any syntax errors in an intelligible fashion. The two types of parsers
employed are: 1. Top down parser:
which build parse trees from top(root) to bottom(leaves) 2. Bottom up parser:
which build parse trees from leaves and work up the root. Reference: {Compilers: Principles, Techniques and Tools. Page No: 171-180}
|
||||||||||||||||||||||||
|
Unit-02/Lecture-03 |
||||||||||||||||||||||||
|
Top down and Bottom-up Parsing: [RGPV, June
2007, Dec 2005] Therefore there are
two types of parsing methods– top-down parsing and bottom-up parsing
(Classifications of parsing is shown below) Sequences of rules are applied in a leftmost derivation in Top-down
parsing. Sequences of rules are applied in a rightmost derivation in Bottom-up
parsing. This is illustrated below. Consider the grammar G with
production ababbb Left parse of the string with the
sequence 1121222. This is known as “Top-down
Parsing.” “Right Parse” is the reversal of sequence of rules applied in a
rightmost derivation. aababbb Right parse of the string with
the sequence 2221121. This is known as “Bottom-up Parsing.” TOP-DOWN
PARSING: The top down construction
of a parse tree is done by starting with the root ,labeled with the starting
non-terminal ,and repeatedly performing the following two steps- (ii)
at node n,
labeled with non-terminal A, select one of the productions for A and
construct children
at n for the symbols on the right side of the production (iii)
Find the next node at which the subtree is
constructed. For some grammars, the above steps can be
implemented during a single left to right scan of the input string. The current
token being scanned on the input is often called as the lookahead symbol. Initially the lookahead symbol is the first
i.e the leftmost token of the input string.
Let us consider the following grammar. A
→ BA| a| aa and
B →BB| b now consider the input string “ bbaa”. The
top-down parsing would look like this in different steps- Here we
have assumed that, at the first attempt the parser would know Which
production to use to get the right output, but in general, the selection of a
production of a non-terminal may involve trial and error, which is we may
have to try a production and backtrack to try another production if the first
is found to be unsuitable. RECURSIVE-DESCENT
PREDICTIVE PARSING: This is
general form of top-down parsing, called recursive descent parsing where
backtracking may be involved. This is a bad type of parsing which involves
repeated trying to get the correct output. This can also be termed as
brute-force type of parsing. Presently, this type of parsing is outdated,
just because there are much better methods of parsing which we will be
discussing later. Consider
the grammar: S →cAd | bd and A → ab | a And the
input string is “cad”. To construct the tree, we create an initial tree of
just one node S. The input pointer points to c, and we use the first
production, for s, To get the expanded tree. The leftmost leaf
labeled c matches the fist symbol of the input and hence we
advance the pointer to the second symbol of the input which is a.
we now expand A by its first production to obtain the following tree. Now we have a match
for the second symbol of the input and hence advance the pointer to d
, and compare it with the next leaf b, which does not match , we
report failure and go back to see whether there is an alternative
production for A. In going back to A, we must back-track the input
pointer to a. finding another production; we try out the next
configuration. Now the leaf a
matches with the second symbol of the input and the third leaf d
match with the third symbol of the input. And because the input string is
consumed, we halt and denote the successful completion of parsing. Reference: {Compilers: Principles,
Techniques and Tools. Page No: 181-182}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-04 |
||||||||||||||||||||||||
|
PREDICTIVE
PARSING: This is a top down parsing
method where we execute a set of recursive set of procedures to process the
input. A procedure is associated with a non-terminal of a grammar. Here the
lookahead symbol unambiguously determines the procedure selected for each
non-terminal. The sequence of procedures called in processing the input
implicitly defines a parse tree for the input. Consider
the grammar: S →cAd | bd and A → ab | e PSEUDO
CODE for a predictive parser input
string: “ced” The
function match() compares the current
lookahead symbol with the argument token
and if matched changes the lookahead symbol by advancing the input
pointer. Parsing begins with a call to the procedure for the starting
non-terminal S in our grammar. Because the lookahead 'c' is in the set { c }
, the function S executes the code: if lookahead is in { c } match(c) , A(),match
(d); once it
matched 'c' , the function A() is called and checks out that the next input
symbol 'e' is then in the set { e } , it executes the code : else if lookahead is in { e
}
match(e); After
the matching of 'e' is over it returns from the function A() and matches the
next token with 'd'. some
important points: Predictive
parsing relies on information about what first symbols can be generated by
right side of a production. If A
→α is a production, then FIRST(α) is defined as the set of
tokens that appear as the first symbols of one or more strings generated from
ß . so
obviously if A→α and
A→ β are two
productions And if
FIRST(α) ,
FIRST(β) are not disjoint , then this parsing would
falter. Also,
this parsing would falter if there is LEFT RECURSION in the grammar. In that
case the parser will loop forever. Consider
the left recursive production expr→expr
+ term, Suppose the procedure
for expr decides to apply this production. The right side begins with
expr so the procedure for expr is called recursively and the
parser loops forever. Note that the lookahead symbol changes only when a
terminal in the right side is matched. Since the production begins with the
non-terminal expr , no changes to the input take place between
recursive calls , causing the infinite loop. FIRST AND FOLLOW: [RGPV, Dec 2009, June 2009] · To compute FIRST(X)
for all grammar symbols X, apply the following rules until no more terminals
or e can be added to any FIRST set. 1. If X
is terminal, then FIRST(X) is {X}. 2. If
X→εis a production, then add ε to FIRST(X). 3. If X
is nonterminal and X->Y1Y2...Yk is a production, then place a in FIRST(X)
if for some i, a is in FIRST(Yi) and εis in all of
FIRST(Y1),...,FIRST(Yi-1) that is, Y1.......Yi-1 · To compute the FOLLOW(A)
for all non-terminals A, apply the following rules until nothing can be added
to any FOLLOW set. 1. Place
$ in FOLLOW(S), where S is the start symbol and $ in the input right
end-marker. 2. If
there is a production A=>aBs where FIRST(s) except e is placed in
FOLLOW(B). 3. If
there is aproduction A->aB or a production A->aBs where FIRST(s)
contains e, then everything in FOLLOW(A) is in FOLLOW(B). Consider
the following example to understand the concept of First and Follow. Find the
first and follow of all non-terminals in the Grammar- For
example, id and left parenthesis are added to FIRST(F) by rule 3 in
definition of FIRST with i=1 in each case, since FIRST(id)=(id) and
FIRST('(')= {(} by rule 1. Then by rule 3 with i=1, the production T →
FT' implies that id and left parenthesis belong to FIRST(T) also. To
compute FOLLOW,we put $ in FOLLOW(E) by rule 1 for FOLLOW. By rule 2 applied
toproduction F→ (E), right parenthesis is also in FOLLOW(E). By rule 3
applied to production E→ TE', $
and right parenthesis are in FOLLOW(E'). Reference: {Compilers: Principles,
Techniques and Tools. Page No: 182-189}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-05 |
||||||||||||||||||||||||
|
·
CONSTRUCTION OF PREDICTIVE PARSING
TABLE: For any
grammar G, the following algorithm can be used to construct the predictive
parsing table. The algorithm is Input: Grammar
G Output: Parsing table M Method 1. For
each production A→ a of the grammar, do steps 2 and 3. 2. For
each terminal a in FIRST(a), add A→a, to M[A,a]. 3. If e
is in First(a), add A→a to M[A,b] for each terminal b in FOLLOW(A). If
e is in FIRST(a) and $ is in FOLLOW(A), add A->a to M[A,$]. 4. Make
each undefined entry of M be error. LL(1) GRAMMAR: [RGPV Dec 2014, Dec
2009] The above algorithm can be applied to any grammar G
to produce a parsing table M. For some Grammars, for example if G is left
recursive or ambiguous, then M will have at least one multiply-defined entry.
A grammar whose parsing table has no multiply defined entries is said to be
LL(1). It can be shown that the above algorithm can be used to produce for
every LL(1) grammar G a parsing table M that parses all and only the
sentences of G. LL(1) grammars have several distinctive properties. No
ambiguous or left recursive grammar can be LL(1). There remains a question of
what should be done in case of multiply defined entries. One easy solution is
to eliminate all left recursion and left factoring, hoping to produce a
grammar which will produce no multiply defined entries in the parse tables.
Unfortunately there are some grammars which will give an LL(1) grammar after
any kind of alteration. In general, there are no universal rules to convert
multiply defined entries into single valued entries without affecting the
language recognized by the parser. The main difficulty in using predictive
parsing is in writing a grammar for the source language such that a
predictive parser can be constructed from the grammar. Although left
recursion elimination and left factoring are easy to do, they make the
resulting grammar hard to read and difficult to use the translation purposes.
To alleviate some of this difficulty, a common organization for a parser in a
compiler is to use a predictive parser for control constructs
and to use operator precedence for expressions. However, if an LR parser
generator is available, one can get all the benefits of predictive parsing
and operator precedence automatically. Reference: {Compilers: Principles,
Techniques and Tools. Page No: 191-192} LR PARSING: :[RGPV,
Dec 2013] INTRODUCTION: The "L" is for
left-to-right scanning of the input and the "R" is for constructing
a rightmost derivation in reverse WHY LR PARSING: ·
LR parsers can be constructed to recognize virtually
all programming-language constructs for which context-free grammars can be
written. ·
The LR parsing method is the most general
non-backtracking shift-reduce parsing method known, yet it can be implemented
as efficiently as other shift-reduce methods. ·
The class of grammars that can be parsed using LR
methods is a proper subset of the class of grammars that can be parsed with
predictive parsers. ·
An LR parser can detect a syntactic error as soon as
it is possible to do so, on a left-to-right scan of the input. The disadvantage is that it takes too much work to construct
an LR parser by hand for a typical programming-language grammar. But there
are lots of LR parser generators available to make this task easy. MODELS OF LR PARSERS The schematic form of an LR parser is shown below. The program uses a stack to store a string of the
form s0X1s1X2...Xmsm where sm is on top. Each Xi is a grammar symbol and each
si is a symbol representing a state. Each state symbol summarizes the
information contained in the stack below it. The combination of the state
symbol on top of the stack and the current input symbol are used to index the
parsing table and determine the shift-reduce parsing decision. The parsing
table consists of two parts: a parsing action function action and a goto
function goto. The program driving
the LR parser behaves as follows: It determines sm the state currently on top
of the stack and ai the current input symbol. It then consults action[sm,ai],
which can have one of four values: ·
shift s, where s is a state ·
reduce by a grammar production A→b ·
accept ·
error The function goto takes a state and grammar symbol
as arguments and produces a state. For a parsing table constructed for a
grammar G, the goto table is the transition function of a deterministic
finite automaton that recognizes the viable prefixes of G. Recall that the
viable prefixes of G are those prefixes of right-sentential forms that can
appear on the stack of a shift-reduce parser because they do not extend past
the rightmost handle. A configuration of an LR parser is a pair whose first
component is the stack contents and whose second component is the unexpended
input: (s0 X1 s1 X2 s2... Xm sm, ai ai+1... an$) This configuration
represents the right-sentential form X1 X1 ... Xm ai ai+1 ...an in
essentially the same way a shift-reduce parser would; only the presence of
the states on the stack is new. Recall the sample parse we did in which we
assembled the right-sentential form by concatenating the remainder of the
input buffer to the top of the stack. The next move of the parser is
determined by reading ai and sm, and consulting the parsing action table
entry action[sm, ai]. Note that we are just looking at the state here and no
symbol below it. We'll see how this actually works later. The configurations resulting after each of
the four types of move are as follows: If action[sm, ai] = shift s, the parser executes a
shift move entering the configuration (s0 X1 s1 X2 s2... Xm sm ai s, ai+1... an$). Here
the parser has shifted both the current input symbol ai and the next symbol.
If action[sm, ai] = reduce A → b, then the parser executes a reduce
move, entering the configuration, (s0 X1 s1 X2 s2... Xm-r sm-r A s, ai
ai+1... an$) where s = goto[sm-r, A] and r is the length of b, the right side
of the production. The parser first popped 2r symbols off the stack (r state
symbols and r grammar symbols), exposing state sm-r. The parser then pushed
both A, the left side of the production, and s, the entry for goto[sm-r, A],
onto the stack. The current input symbol is not changed in a reduce move. The
output of an LR parser is generated after a reduce move by executing the
semantic action associated with the reducing production. For example, we
might just print out the production reduced. If action[sm, ai] = accept, parsing is completed. Reference: {Compilers: Principles,
Techniques and Tools. Page No: 215-220}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-06 |
||||||||||||||||||||||||
|
SHIFT REDUCE PARSING: [RGPV Dec 2014]
A shift-reduce parser uses a parse stack which contains grammar
symbols. During the operation of the parser, symbols from the input are
shifted onto the stack. If a prefix of the symbols on top of the stack
matches the RHS of a grammar rule which is the correct rule to use within the
current context, then the parser reduces the RHS of the rule to its LHS, replacing
the RHS symbols on top of the stack with the non-terminal occurring on the
LHS of the rule. This shift-reduce process continues until the parser
terminates, reporting either success or failure. It terminates with success
when the input is legal and is accepted by the parser. It terminates with
failure if an error is detected in the input. The parser is nothing but a
stack automaton which may be in one of several discrete states. A state is
usually represented simply as an integer. In reality, the parse stack
contains states, rather than grammar
symbols. However, since each state corresponds to a unique grammar symbol,
the state stack can be mapped onto the grammar symbol stack mentioned
earlier. The operation of the parser is controlled by a couple
of tables: Parsing Conflicts in
Shift-Reduce Parsing 1. Shift-Reduce Conflict 2. Reduce-Reduce Conflict Construction
of ACTION and GOTO Tables: [RGPV, Dec 2009] ·
ACTION TABLE The action table is a table with rows indexed by
states and columns indexed by terminal Symbols. When the parser is in some
state s and the current lookahead terminal is t, the action taken by the
parser depends on the contents of action[s][t], which can contain four
different kinds of entries: Shift s': Shift
state s' onto the parse stack. Reduce r: Reduce by
rule r. This is explained in more detail below. Accept: Terminate
the parse with success, accepting the input. Error: Signal a
parse error ·
GOTO TABLE The goto table is a table with rows indexed by
states and columns indexed by non-terminal symbols. When the parser is in
state s immediately after reducing by rule N, then the next state to enter is
given by goto[s][N]. The current state of a shift-reduce parser is the
state on top of the state stack. The detailed operation of such a parser is as follows: 1. Initialize the parse stack to contain a single
state s0, where s0 is the distinguished initial state of the parser. 2. Use the state s on top of the parse stack and the
current lookahead t to consult the action table entry action[s][t]: · If the action table entry is shift s' then push state s' onto the
stack and advance the input so that the lookahead is set to the next
token. · If the action table entry is reduce r and rule r has m symbols in its
RHS, then pop m symbols off the parse stack. Let s' be the state
now revealed on top of the parse stack and N be the LHS non-terminal for rule
r. Then consult the goto table and push the state given by goto[s'][N] onto
the stack. The lookahead token is not changed by this step. · If the action table entry is accept, then terminate the parse with
success. · If the action table entry is error, then signal an error. 3. Repeat step (2) until the parser terminates. For example, consider the following simple grammar 0) $S: stmt <EOF> 1) stmt: ID ':=' expr 2) expr: expr '+' ID 3) expr: expr '-' ID 4) expr: ID Which describes assignment statements like a := b +
c - d. (Rule 0 is a special augmenting production added to the grammar). One possible set of shift-reduce parsing tables is
shown below (sn denotes shift n, rn denotes reduce n, acc denotes accept and
blank entries denote error entries): Parser Tables Reference: {Compilers: Principles,
Techniques and Tools. Page No: 195-199}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-07 |
||||||||||||||||||||||||
|
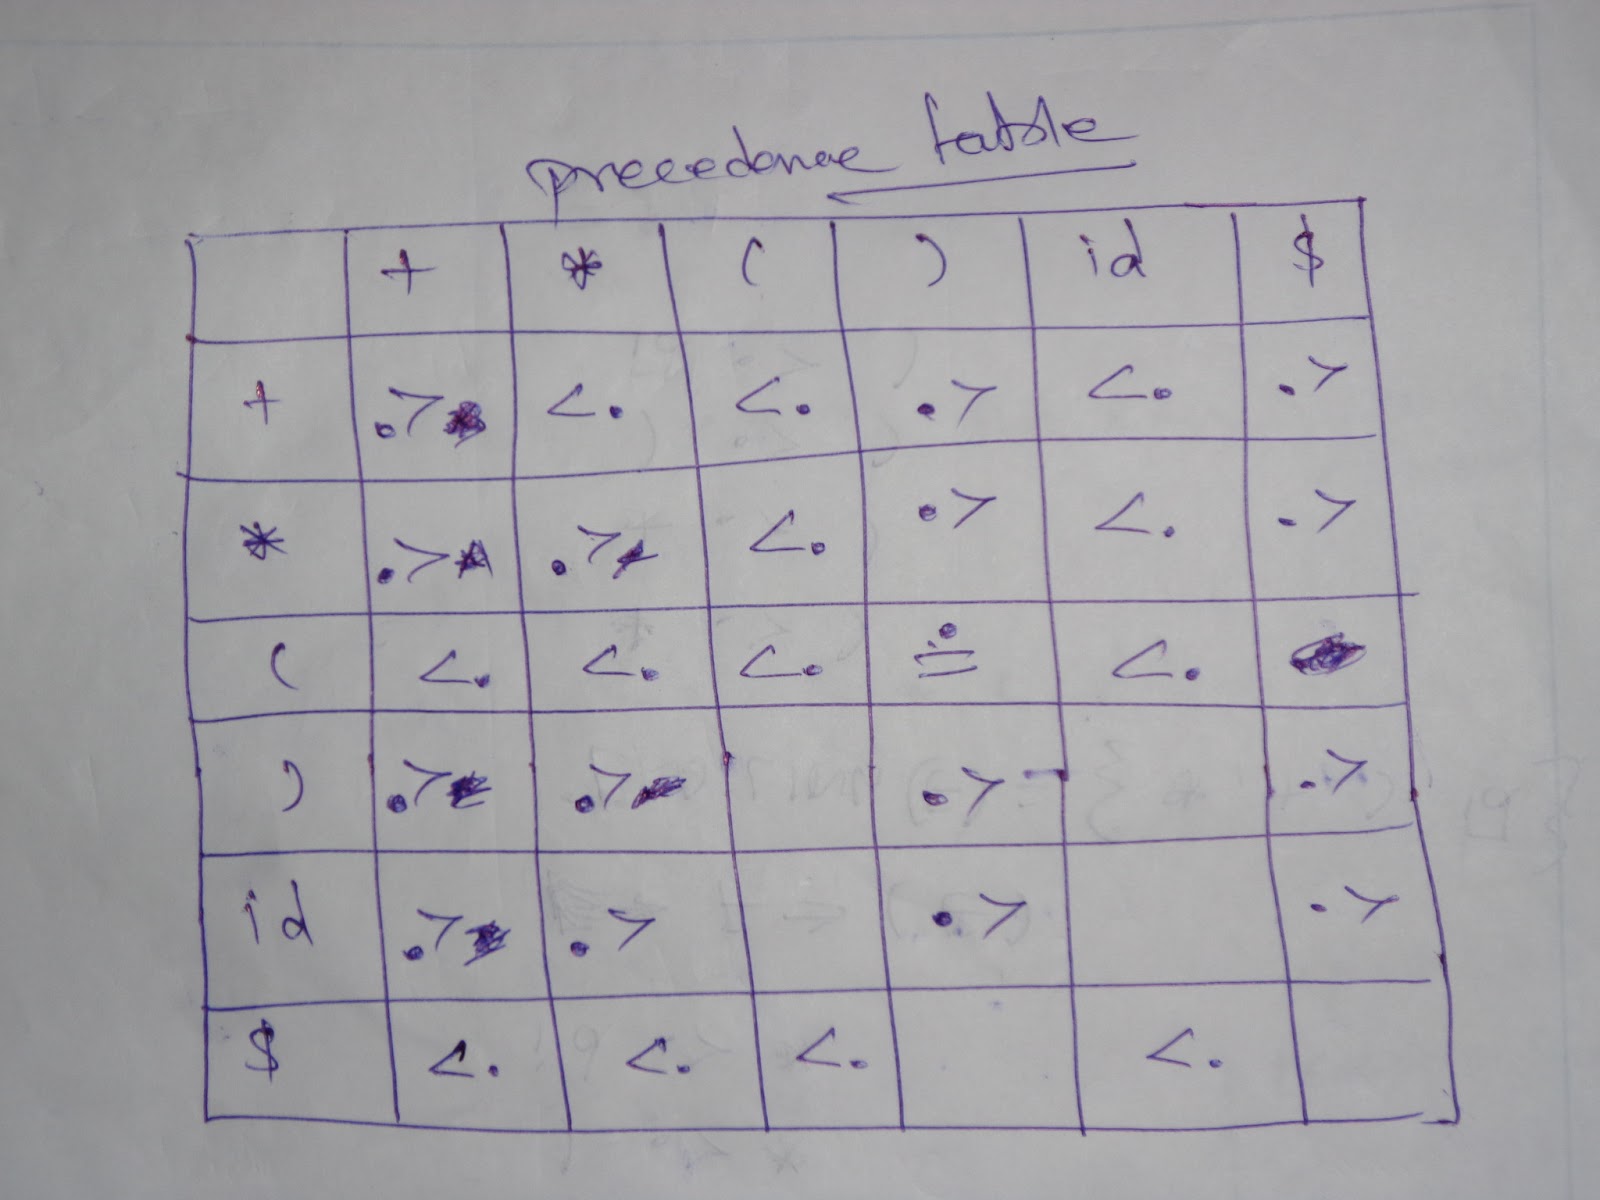
OPERATOR PRECEDENCE PARSING: [RGPV, Dec 2007, 2005] Precedence Relations Bottom-up
parsers for a large class of context-free grammars can be easily developed
using operator grammars. Operator grammars have the property that no
production right side is empty or has two adjacent non-terminals. This
property enables the implementation of efficient operator-precedence parsers.
These parser rely on the following three precedence relations: Relation
Meaning a
<· b a yields precedence to b a =·
b a has the same precedence as b a ·> b a takes precedence over b These operator precedence relations
allow delimiting the handles in the right sentential forms: <· marks the
left end, =· appears in the interior of the handle, and ·> marks the right
end. Example: Consider the grammar E→E+E E→E*E E→id The input string: id1 + id2 * id3 after inserting precedence relations becomes $ <· id1 ·> + <· id2 ·> *
<· id3 ·> $ Having precedence relations allows to identify
handles as follows: ·
scan the string from left until seeing ·> ·
scan backwards the string from right to left until
seeing <· ·
everything between the two relations <· and ·>
forms the handle OPERATOR PRECEDENCE PARSING ALGORITHM [RGPV, June 2007, Dec 2005] Initialize: Set ip to point to the first symbol of w $ Repeat: Let X be the top stack symbol, and a the symbol pointed to by
ip if $ is on the top of the stack and ip points to $ then return else Let a be the top terminal on the stack, and b the symbol pointed to by ip if a <· b or a =· b then push b onto the stack advance ip to the next input symbol else if a ·> b then repeat pop the stack until the top stack terminal is related by <· to the terminal most recently popped else error() end Reference: {Compilers: Principles,
Techniques and Tools. Page No: 203-206}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-08 |
||||||||||||||||||||||||
|
Construction of Operator
Precedence Parsing
Table: [RGPV, Dec
2005] Operator Grammars: no production right side is e or has two adjacent non-terminals. Precedence Relations In operator-precedence parsing, we define three disjoint precedence
relations between certain pairs of terminals. a =.b
b has same precedence as a a .>
b b has lower precedence than a The determination of correct precedence relations between terminals
are based on the traditional notions of associativity and precedence of
operators. (Unary minus causes a problem). Methods Two Methods to determine a precedence relation between a pair of
terminals 1. Based on associativity and precedence relations of operators 2. Using Operator Precedence Grammar Compute LEADING (A) • LEADING (A) = {a| A → γaδ, where γ is ε or
a single non-terminal.} • Rule 1: a is in LEADING (A) if there is a production of the form A
→ γaδ, Where γ is ε or a single non-terminal • Rule 2: a is in LEADING (B) and if there is a production of the form
A → Bα, then a is in LEADING (A) Compute TRAILING (A) • TRAILING (A) = {a| A → γaδ, where δ is ε
or a single non-terminal.} • Rule 1: a is in TRAILING (A) if there is a production of the form A
→ γaδ, Where δ is ε or a single non-terminal • Rule 2: a is in TRAILING (B) and if there is a production of the
form A → αB, then a is in TRAILING (A) Example: Operator Precedence Parsing Table: ALGORITHM FOR CONSTRUCTING PRECEDENCE FUNCTIONS [RGPV, Dec 2005] 1. Create functions fa for each grammar terminal a and for the end of
string symbol; 2. Partition the symbols in groups so that fa and gb are in the same
group if a =· b ( there can be symbols in the same group even if they are not connected by
this relation) 3. Create a directed graph whose nodes are in the groups, next for
each symbols a and b do: place an edge from the group of gb to the group of fa if a <·
b, otherwise if a ·> b place an edge from the group of fa to that of gb; 4. If the constructed graph has a cycle then no precedence functions
exist. When there are no cycles collect the length of the longest paths from the groups of
fa and gb Example: Consider the above table Using the algorithm leads
to the following graph: Precedence Functions are:
Reference: {Compilers: Principles,
Techniques and Tools. Page No: 207-210}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-10 |
||||||||||||||||||||||||
|
SLR PARSER: [RGPV Dec 2013, Dec 2008] An LR(0) item (or just item) of a
grammar G is a production of G with a dot at some position of
the right side indicating how much of a production we have seen up to a given
point. For example, for the production E → E + T we
would have the following items: [E→.E + T] [E→E. + T] [E→E +. T] [E→E + T.] ALGORITHM FOR CONSTRUCTING AN SLR PARSING TABLE Input: augmented grammar G' Output: SLR parsing table functions action and goto for G'
Method: Construct C = {I0, I1 , ..., In} the collection of
sets of LR(0) items for G'. State i is constructed from Ii: if [A → a.ab] is in Ii and goto(Ii, a) = Ij,
then set action[i, a] to "shift j". Here a must be a terminal. if [A → a.] is in Ii, then set action[i, a] to
"reduce A -> a" for all a in FOLLOW(A). Here A may not be S'. if [S' → S.] is in Ii, then set action[i, $]
to "accept" If any conflicting actions are generated by these
rules, the grammar is not SLR(1) and the algorithm fails to produce a parser.
The goto transitions for state i are constructed for all non-terminals
A using the rule: If goto(Ii, A)= Ij, then goto[i, A] = j. All entries not defined by rules 2 and 3 are made
"error". The initial state of the parser is the one
constructed from the set of items containing [S' → .S]. Let's
work an example to get a feel for what is going on, Example: The Action and Goto Table The two LR(0) parsing
tables for this grammar look as follows:
Reference: {Compilers: Principles,
Techniques and Tools. Page No: 216-220} |
||||||||||||||||||||||||
|
Unit-2/Lecture-11 |
||||||||||||||||||||||||
|
CONSTRUCTING THE SLR PARSING TABLE: :[RGPV, Dec 2013, 2008] To construct the parser table we must convert our
NFA into a DFA. The states in the LR table will be the e-closures of the
states corresponding to the items SO...the process of creating the LR state
table parallels the process of constructing an equivalent DFA from a machine
with e-transitions. Been there, done that - this is essentially the subset
construction algorithm so we are in familiar territory here. We need two operations: closure() and goto(). closure() If I is a set of items for a grammar G, then
closure(I) is the set of items constructed from I by the two rules: Initially
every item in I is added to closure(I) If A→a.Bb is in closure(I), and B
→ g is a production, then add the initial item [B →
.g] to I, if it is not already there. Apply this rule until no more new items
can be added to closure(I). From our grammar above, if I is the set of one item
{[E'→ .E]}, then closure(I) contains: I0: E' → .E E → .E + T E → .T T → .T * F T → .F F →.(E) F → .id goto()
goto(I, X), where I is a set of items and
X is a grammar symbol, is defined to be the closure of the set of all
items [A →aX.b] such that [A→a.Xb]
is in I. The idea here is fairly intuitive: if I is the set of items that
are valid for some viable prefix g, then goto(I, X) is the set of
items that are valid for the viable prefix gX. SETS-OF-ITEMS-CONSTRUCTION To construct the canonical collection of sets of
LR(0) items for Augmented grammar G'. procedure items(G') begin C := {closure({[S' -> .S]})}; repeat for each set of items in C and each grammar symbol X
such that goto(I, X) is not empty and not in C do add goto(I, X) to C; until no more sets of items can be added to C end; ALGORITHM FOR CONSTRUCTING AN SLR PARSING TABLE Input: augmented grammar G' Output: SLR parsing table functions action and goto for G'
Method: Construct C = {I0, I1 , ..., In} the collection of
sets of LR(0) items for G'. State i is constructed from Ii: if [A → a.ab] is in Ii and goto(Ii, a) = Ij,
then set action[i, a] to "shift j". Here a must be a terminal. if [A → a.] is in Ii, then set action[i, a] to
"reduce A -> a" for all a in FOLLOW(A). Here A may not be S'. if [S' → S.] is in Ii, then set action[i, $]
to "accept" If any conflicting actions are generated by these
rules, the grammar is not SLR(1) and the algorithm fails to produce a parser.
The goto transitions for state i are constructed for all non-terminals
A using the rule: If goto(Ii, A)= Ij, then goto[i, A] = j. All entries not defined by rules 2 and 3 are made
"error". The initial state of the parser is the one
constructed from the set of items containing [S' → .S]. Let's
work an example to get a feel for what is going on, An Example
(1) E → E * B (2) E → E + B (3) E → B (4) B → 0 (5) B → 1 The Action and Goto Table The two LR(0) parsing
tables for this grammar look as follows: Reference: {Compilers: Principles,
Techniques and Tools. Page No: 221-229}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-12 |
||||||||||||||||||||||||
|
CANONICAL LR
PARSING: [RGPV June 2006, Dec 2008] By splitting states when necessary, we can arrange
to have each state of an LR parser indicate exactly which input symbols can
follow a handle a for which there is a possible reduction to A. As the
text points out, sometimes the FOLLOW sets give too much information and
don’t (can't) discriminate between different reductions. The general form of an LR(k) item becomes [A →a.b,
s] where A → ab is a production and s is a string of terminals. The
first part (A → a.b) is called the core and the second part is the
lookahead. In LR(1) |s| is 1, so s is a single terminal. A → ab is the usual righthand side with a
marker; any a in s is an incoming token in which we are interested. Completed
items used to be reduced for every incoming token in FOLLOW(A), but now we
will reduce only if the next input token is in the lookahead set s. if we get
two productions A → a and B → a, we can tell them apart when a is
a handle on the stack if the corresponding completed items have different
lookahead parts. Furthermore, note that the lookahead has no effect for an
item of the form [A → a.b, a] if b is not e. Recall that our problem
occurs for completed items, so what we have done now is to say that an item
of the form [A → a., a] calls for a reduction by A → a only if
the next input symbol is a. More formally, an LR(1) item [A →a.b, a] is
valid for a viable prefix g if there is a derivation S ALGORITHM FOR CONSTRUCTION OF THE SETS OF LR(1)
ITEMS Input: grammar G' Output: sets of LR(1) items that are the set of
items valid for one or more viable prefixes of G' Method: Consider the following grammar, S’→S S→CC C→cC C→d Reference: {Compilers: Principles,
Techniques and Tools. Page No: 223-235}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-13 |
||||||||||||||||||||||||
|
CONSTRUCTION OF THE CANONICAL LR PARSING TABLE (ALGORITHM): Input: grammar G' Output: canonical LR parsing table functions action and
goto 1. Construct C = {I0, I1 , ..., In} the collection
of sets of LR(1) items for G'. State i is constructed from Ii. 2. if [A -> a.ab, b>] is in Ii and
goto(Ii, a) = Ij, then set action[i, a] to "shift j". Here a must
be a terminal. 3. if [A -> a., a] is in Ii, then set
action[i, a] to "reduce A -> a" for all a in FOLLOW(A).
Here A may not be S'. 4. if [S' -> S.] is in Ii, then set
action[i, $] to "accept" 5. If any conflicting actions are generated by these
rules, the grammar is not LR(1) and the algorithm fails to produce a parser. 6. The goto transitions for state i are constructed
for all nonterminals A using the rule: If goto(Ii, A)= Ij, then
goto[i, A] = j. 7. All
entries not defined by rules 2 and 3 are made "error". 8. The inital
state of the parser is the one constructed from the set of items containing [S'
-> .S, $]. Construction
of the sets of LR(1) items Input: An
augmented grammar G’. Output: The sets
of LR(1) items that are the set of items valid for one or more viable
prefixes of G’ . Method: function closure(I); begin repeat for each item [Aà α. Bβ, a]
in I, each production Bàγin G', and each terminal b in FIRST(βa) such that [Bà. γ, b]
is not in I do add [Bà. γ, b]
to I until no more sets of items can be added to I end return I end; function goto(I,
X) begin let J be the set of items [AàX. β, a]
such that [Aà X
β, a] is in I return closure(J) end; procedure items(G')
begin C := {closure({S'à. S,$})}; repeat for each set of items I in C and
each grammar symbol X such that goto(I , X) is not
empty and not in C do add goto(I , X) to C until no more sets of items can be added to
C end; Consider the following augmented grammar:- S’à S Sà CC Cà Cc | d The initial set of items is:- I0 : S’
à .S , $ Sà .CC, $ Cà .Cc, c | d Cà .d, c | d We have next set of items as:- I1
: S’ à S., $ I2
: S à .Cc, $ C à .Cc, $ C à .d, $ I3
: C à c.C, $ C à .c C , c | d C à .d, $ I4
: C à d. , c |
d I5 : S à CC. , $ I6 : C à c.C, $ C à .c C ,$ C à .d , $ I7 : C à d. , $ I8
: C à c C. , c | d I9
: C à c C. , $ Reference: {Compilers: Principles,
Techniques and Tools. Page No: 223-235} |
||||||||||||||||||||||||
|
Unit-2/Lecture-14 |
||||||||||||||||||||||||
|
LALR PARSER: [RGPV, June
2006] We begin with two observations. First, some of the
states generated for LR(1) parsing have the same set of core (or first)
components and differ only in their second component, the lookahead symbol.
Our intuition is that we should be able to merge these states and reduce the
number of states we have, getting close to the number of states that would be
generated for LR(0) parsing. This observation suggests a hybrid approach: We
can construct the canonical LR(1) sets of items and then look for sets of
items having the same core. We merge these sets with common cores into one
set of items. The merging of states with common cores can never produce a
shift/reduce conflict that was not present in one of the original states
because shift actions depend only on the core, not the lookahead. But it is
possible for the merger to produce a reduce/reduce conflict. Our second
observation is that we are really only interested in the lookahead symbol in
places where there is a problem. So our next thought is to take the LR(0) set
of items and add lookaheads only where they are needed. This leads to a more
efficient, but much more complicated method. ALGORITHM FOR EASY CONSTRUCTION OF AN LALR TABLE Input: G' Output: LALR parsing table functions with action and
goto for G'. Method: 1. Construct C = {I0, I1 , ..., In} the collection
of sets of LR(1) items for G'. 2. For each core present among the set of LR(1)
items, find all sets having that core and replace these sets by the union. 3. Let C' = {J0, J1 , ..., Jm} be the resulting sets
of LR(1) items. The parsing actions for state i are constructed from Ji in
the same manner as in the construction of the canonical LR parsing table. 4. If there is a conflict, the grammar is not
LALR(1) and the algorithm fails. 5. The goto table is constructed as follows: If J is
the union of one or more sets of LR(1) items, that is, J = I0U I1 U ... U Ik,
then the cores of goto(I0, X), goto(I1, X), ..., goto(Ik, X) are the same,
since I0, I1 , ..., Ik all have the same core. Let K be the union of all sets
of items having the same core asgoto(I1, X). 6. Then goto(J, X) = K. Parsing Table I3 & I6 can be replaced by their union I36:C→c.C,c/d/$ C→.Cc,C/D/$ C→.d,c/d/$ I47:C→d.,c/d/$ I89:C→Cc.,c/d/$ ERROR RECOVERY: An LR parser will detect an
error when it consults the parsing action table and find a blank or error
entry. Errors are never detected by consulting the goto table. An LR parser
will detect an error as soon as there is no valid continuation for the
portion of the input thus far scanned. A canonical LR parser will not make
even a single reduction before announcing the error. SLR and LALR parsers may
make several reductions before detecting an error, but they will never shift
an erroneous input symbol onto the stack. PANIC-MODE ERROR RECOVERY: We can
implement panic-mode error recovery by scanning down the stack until a state
s with a goto on a particular non-terminal A is found. Zero or more input
symbols are then discarded until a symbol a is found that can legitimately
follow A. The parser then stacks the state GOTO(s, A) and resumes normal
parsing. The situation might exist where there is more than one choice for
the non-terminal A. Normally these would be non-terminals representing major
program pieces, e.g. an expression, a statement, or a block. For example, if
A is the non-terminal stmt, a might be semicolon or}, which marks the end of
a statement sequence. This method of error recovery attempts to eliminate the
phrase containing the syntactic error. The parser determines that a string
derivable from A contains an error. Part of that string has already been
processed, and the result of this processing is a sequence of states on top
of the stack. The remainder of the string is still in the input, and the
parser attempts to skip over the remainder of this string by looking for a
symbol on the input that can legitimately follow A. By removing states from
the stack, skipping over the input, and pushing GOTO(s, A) on the stack, the
parser pretends that if has found an instance of A and resumes normal
parsing. PHRASE-LEVEL RECOVERY: Phrase-level
recovery is implemented by examining each error entry in the LR action table
and deciding on the basis of language usage the most likely programmer error that
would give rise to that error. An appropriate recovery procedure can then be
constructed; presumably the top of the stack and/or first input symbol would
be modified in a way deemed appropriate for each error entry. In designing
specific error-handling routines for an LR parser, we can fill in each blank
entry in the action field with a pointer to an error routine that will take
the appropriate action selected by the compiler designer. The actions may
include insertion or deletion of symbols from the stack or the input or both,
or alteration and transposition of input symbols. We must make our choices so
that the LR parser will not get into an infinite loop. A safe strategy will
assure that at least one input symbol will be removed or shifted eventually,
or that the stack will eventually shrink if the end of the input has been
reached. Popping a stack state that covers a non terminal should be avoided,
because this modification eliminates from the stack a construct that has
already been successfully parsed. Reference: {Compilers: Principles,
Techniques and Tools. Page No: 236-241}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-15 |
||||||||||||||||||||||||
|
SYNTAX DIRECTED TRANSLATION: [RGPV, Dec 2013] · The
Principle of Syntax Directed Translation states that the meaning of an input
sentence is related to its syntactic structure, i.e., to its Parse-Tree. · By Syntax
Directed Translations we indicate those formalisms for specifying
translations for programming language constructs guided by context-free
grammars. - We associate Attributes to the grammar symbols
representing the language constructs. -Values for attributes are computed by Semantic
Rules associated with grammar productions. · Evaluation
of Semantic Rules may: - Generate Code; - Insert information into the Symbol Table; - Perform Semantic Check; - Issue error messages; There are
two notations for attaching semantic rules: 1. Syntax Directed Definitions. High-level
specification hiding many implementation details (also called Attribute
Grammars). 2. Translation Schemes. More implementation
oriented: Indicate the order in which semantic rules are to be evaluated. Syntax Directed Definitions: • Syntax Directed Definitions are a
generalization of context-free grammars in which: 1. Grammar symbols have an associated set of Attributes;
2. Productions are associated with Semantic Rules
for computing the values of attributes. · Such
formalism generates Annotated Parse-Trees where each node of the tree
is a record with a field for each attribute (e.g., X.a indicates the
attribute a of the grammar symbol X). · The value
of an attribute of a grammar symbol at a given parse-tree node is defined by
a semantic rule associated with the production used at that node. We distinguish between two kinds of attributes: 1. Synthesized Attributes. They are computed
from the values of the attributes of the children nodes. 2. Inherited Attributes. They are computed
from the values of the attributes of both the siblings and the parent nodes Syntax Directed Definitions: An Example • Example. Let us consider the Grammar for arithmetic
expressions. The Syntax Directed Definition associates to each non terminal a
synthesized attribute called val. Reference: {Compilers: Principles,
Techniques and Tools. Page No: 279-285}
|
||||||||||||||||||||||||
|
Unit-2/Lecture-16 |
||||||||||||||||||||||||
|
S-ATTRIBUTED
& L- ATTRIBUTED DEFINITION: [RGPV, Dec 2012, June 2009] S-ATTRIBUTED DEFINITION: Definition: An S-Attributed Definition
is a Syntax Directed Definition that uses only synthesized attributes. • Evaluation Order. Semantic rules in a
S-Attributed Definition can be evaluated by a bottom-up, or Post-Order,
traversal of the parse-tree. • Example. The above arithmetic grammar is an
example of an S-Attributed Definition. The annotated parse-tree for the input
3*5+4n is: L- ATTRIBUTED DEFINITION: Definition: A SDD its L-attributed if
each inherited attribute of Xi in the RHS of A ! X1 : :Xn depends only on 1. attributes of X1;X2; : : : ;Xi (symbols to the
left of Xi in the RHS) 2. inherited attributes of A. Restrictions for translation schemes: 1. Inherited attribute of Xi must be computed by an
action before Xi. 2. An action must not refer to synthesized attribute
of any symbol to the right of that action. 3. Synthesized attribute for A can only be computed
after all attributes it references have been completed (usually at end of
RHS). Reference: {Compilers: Principles,
Techniques and Tools. Page No: 283, 289}
|